Babafig

Rechercher

Découvrez de nouvelles personnes, créez des liens et faites-vous de nouveaux amis

  • AI and Machine Learning in Site Reliability Engineering: What’s Changing in 2025
    Site Reliability Engineering (SRE) has always been about balancing reliability with innovation. In 2025, the shift is clear—AI and Machine Learning (ML) are no longer optional, they’re core enablers of reliability. From predictive monitoring to automated incident response, AI-driven tools are redefining how IT teams ensure uptime, scalability, and performance.

    The Growing Role of AI in Reliability

    According to a Gartner 2024 report, organizations that adopt AI in IT operations (AIOps) see a 30% reduction in unplanned downtime and a 40% improvement in incident response speed. Traditional monitoring tools can detect anomalies, but AI goes further—it predicts failures before they occur.
    For example, an ML algorithm analyzing CPU, memory, and network patterns can identify unusual spikes days in advance, alerting engineers proactively. This predictive approach means fewer service disruptions and better customer experiences.

    Case Study: Google’s Predictive Reliability Model

    Google, the birthplace of SRE, has been integrating AI into reliability practices for years. In a 2024 case study, Google shared how its machine learning models reduced false-positive alerts by 60% across its cloud infrastructure. This not only freed engineers from alert fatigue but also allowed them to focus on high-value problem-solving.
    Another example is Netflix, which uses ML-driven chaos testing. By simulating unpredictable failures, their SRE Course trains AI models to respond faster, ensuring streaming reliability for over 270 million global users.

    Expert Perspectives on AI in SRE

    “AI is no longer about replacing engineers—it’s about augmenting them,” says Charity Majors, CTO of Honeycomb.io. “The future SRE isn’t just a systems thinker, but also an AI collaborator.”

    Similarly, Google Cloud’s SRE Director Ben Treynor Sloss recently emphasized that “machine learning in reliability engineering helps teams move from reactive firefighting to proactive reliability.” This shift enables organizations to scale without scaling engineering headcount linearly.

    What’s Changing in 2025

    Predictive Monitoring Becomes Standard

    Tools like Datadog and Dynatrace are embedding ML models to anticipate outages. By 2025, predictive monitoring will be a default, not a luxury.


    Automated Incident Response

    AI-powered runbooks can auto-resolve recurring issues. For example, restarting services, clearing cache, or reallocating resources can now happen without human intervention.


    AI-Enhanced Postmortems

    Post-incident analysis is moving beyond human memory. ML can analyze logs, metrics, and traces to provide unbiased root cause analysis.


    Focus on Ethical AI in Reliability

    As AI grows in SRE, questions around transparency, bias, and accountability will dominate discussions in 2025. Engineers must ensure AI decisions are explainable.


    Data-Backed Impact of AI in Reliability

    IDC predicts that by 2026, 65% of enterprises will rely on AI to reduce downtime costs.


    Forrester research shows that enterprises adopting AIOps save an average of $2.5 million annually on operational inefficiencies.


    According to Uptime Institute’s 2024 survey, human error still accounts for 70% of outages—a gap AI can significantly reduce.


    How NovelVista’s SRE Certification Can Boost Your Career

    As AI reshapes SRE, professionals must bridge the gap between reliability practices and intelligent automation. This is where NovelVista’s SRE Foundation Training becomes a game-changer. The program doesn’t just cover traditional SRE concepts like SLIs, SLOs, and SLAs—it integrates real-world applications of AI and automation in reliability engineering.

    By completing the certification, IT professionals gain:
    Hands-on exposure to modern tools like AIOps platforms.


    Insights into AI-driven incident management.


    A globally recognized credential that positions you as a future-ready reliability engineer.


    For IT leaders, this certification ensures your teams are equipped to handle the AI-powered reliability era of 2025 and beyond.

    Final Thoughts

    AI and Machine Learning are no longer buzzwords in Site Reliability Engineering—they’re the driving forces behind operational excellence in 2025. From predictive insights to automated incident response, the landscape is shifting rapidly. Engineers who adapt will thrive, and organizations that embrace AI in reliability will save millions in downtime costs.
    For professionals, the next step is clear: upskill in AI-driven reliability practices through structured training like NovelVista’s SRE certification. In a world where every second of uptime matters, AI is the new currency of reliability.
    10.9k Vues
  • Why IT Professionals Should Upskill with SRE

    In the digital era, every second of downtime can cost businesses revenue, customers, and reputation. IT teams are no longer just support functions—they are the backbone of innovation and business continuity. As organizations scale rapidly and embrace cloud-native technologies, the demand for systems that are reliable, automated, and resilient is higher than ever. This shift has made Site Reliability Engineering (SRE) one of the most valuable skill sets for IT professionals who want to stay relevant and advance their careers.


    What is Site Reliability Engineering (SRE)?

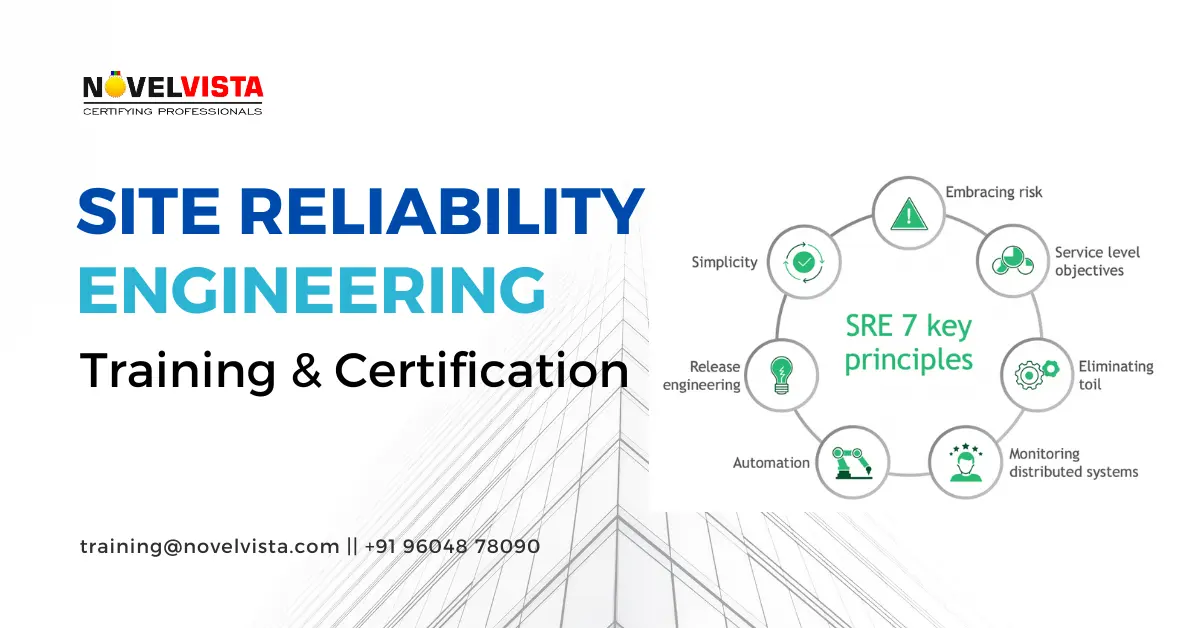
    Site Reliability Engineering, pioneered by Google, is a discipline that applies software engineering principles to IT operations. The goal is to create scalable and highly reliable systems by automating tasks, managing incidents, and improving service delivery. Unlike traditional IT roles, SRE Training emphasizes proactive problem-solving, automation, and continuous improvement rather than reactive firefighting.

    For IT professionals, SRE is the next logical step in their career path. It combines coding, systems administration, and operations into a role that is highly valued in today’s cloud-driven business environment.

    Why IT Professionals Should Learn SRE

    1. Growing Demand in the Job Market
    Organizations worldwide are facing downtime costs that can run into millions. As a result, companies are aggressively hiring professionals with SRE skills to ensure uptime and system reliability. According to recent industry surveys, SRE roles rank among the fastest-growing positions in IT. By learning SRE, IT professionals gain access to higher-paying jobs and greater career mobility.

    2. Relevance in a Cloud-First World
    With the rise of cloud computing, DevOps, and containerization (Kubernetes, Docker), IT operations have become more complex. Traditional IT skillsets often fall short in handling modern distributed systems. SRE equips professionals with the ability to manage these environments effectively, ensuring performance and resilience even at scale.

    3. Enhancing Problem-Solving Skills
    Traditional IT roles often revolve around responding to issues after they occur. SRE shifts this mindset towards prevention through automation and monitoring. IT professionals who upskill with SRE learn to design systems that detect and fix issues before they impact end-users, making them invaluable assets to any organization.

    4. Aligning with DevOps and Agile
    SRE is closely aligned with DevOps and Agile methodologies, which dominate today’s IT landscape. Upskilling with SRE ensures IT professionals remain relevant, as organizations increasingly seek individuals who can collaborate across teams, reduce silos, and accelerate delivery without compromising reliability.

    5. Career Growth and Higher Salaries
    SRE professionals command premium salaries due to their specialized skill set. Employers recognize the value of having staff who can optimize performance, reduce downtime, and deliver better user experiences. For IT professionals looking to boost their career, mastering SRE offers a direct path to leadership roles in reliability and operations.

    How IT Professionals Can Upskill in SRE

    Upskilling in SRE doesn’t require starting from scratch. IT professionals can build on their existing experience with system administration, networking, or DevOps. The key steps include:
    Enroll in SRE Certification Training: Structured courses provide hands-on skills in automation, incident management, and reliability practices.

    Learn Key Tools and Frameworks: Tools like Prometheus, Grafana, Terraform, and Kubernetes are central to SRE practices.

    Adopt a Coding Mindset: Gaining proficiency in Python, Go, or Shell scripting helps automate repetitive tasks.

    Practice with Real-World Scenarios: Simulating outages, monitoring performance, and handling incidents strengthen reliability expertise.

    By investing in a professional SRE certification, IT professionals not only validate their skills but also gain recognition in the global job market.

    Final Thoughts

    The IT industry is evolving rapidly, and roles that rely solely on traditional operations skills are becoming outdated. Companies today need IT professionals who can ensure reliability, scalability, and automation in complex digital environments. That’s exactly what SRE delivers.
    For IT professionals, upskilling with an SRE Course is more than just an option—it’s a future-proof investment in their career. By mastering SRE principles and tools, you position yourself at the forefront of innovation, ensuring long-term relevance and success in the ever-changing technology landscape.
    12.4k Vues
  • Advanced SRE Learning Paths: Building Expertise Beyond the Basics

    Site Reliability Engineering (SRE) has become a cornerstone for modern organizations that depend on scalable, reliable, and high-performing digital services. While entry-level SRE skills focus on monitoring, incident response, and automation basics, advanced SRE learning paths take professionals deeper into resilience engineering, systems design, and leadership. For engineers looking to future-proof their careers, mastering these advanced pathways is essential.

    In this article, we’ll explore the key components of advanced SRE learning paths, why they matter, and how to strategically navigate them for long-term career growth.

    Why Advanced SRE Learning Matters

    Basic SRE training helps engineers manage day-to-day operations, but scaling digital infrastructure requires more. Advanced learning empowers professionals to:

    Solve complex system failures with deep root cause analysis.

    Architect resilient platforms capable of handling global traffic surges.

    Balance reliability with innovation, aligning with business objectives.

    Lead SRE teams, shaping incident management culture and engineering practices.

    Organizations are increasingly seeking SRE leaders who not only keep systems up but also drive reliability as a business enabler.

    Core Pillars of Advanced SRE Learning Paths

    The SRE Certifications are not just about technical depth—they blend systems thinking, leadership, and business alignment. Here are the major focus areas:

    1. Systems Architecture and Scalability

    At the advanced level, SREs must understand distributed systems at scale. This includes:
    Designing fault-tolerant, multi-region architectures.

    Mastering microservices orchestration with Kubernetes, Istio, and service meshes.

    Applying chaos engineering to test resilience under failure conditions.

    2. Observability and Advanced Monitoring

    Beyond logs and dashboards, advanced observability emphasizes:
    Implementing OpenTelemetry for unified tracing.

    Predictive monitoring using machine learning and AIOps.

    Building proactive alerting systems that reduce noise and false positives.

    3. Reliability Engineering at Scale
    Advanced SRE paths focus on error budgets and service-level objectives (SLOs) at organizational scale. Engineers learn:

    How to design SLOs that align with customer expectations.

    Automating error budget policies into deployment pipelines.

    Driving conversations between engineering and business stakeholders on risk trade-offs.

    4. Security and Compliance Integration

    Modern SREs cannot ignore security. Advanced learning integrates:
    DevSecOps practices into reliability pipelines.

    Infrastructure as Code (IaC) security.

    Compliance automation for standards like ISO, SOC 2, or GDPR.

    5. Leadership and Cultural Development

    At this stage, SREs evolve into leaders. Key skills include:
    Building blameless postmortem cultures.

    Mentoring junior engineers and fostering continuous learning.

    Influencing cross-functional teams to adopt reliability-first practices

    Structured Learning Path for Advanced SREs

    To master these pillars, professionals can follow a structured roadmap:
    Deep Technical Specialization – Advanced courses in distributed systems, cloud-native design, and observability.

    Certifications & Training – Programs like Google’s Professional Cloud DevOps Engineer or vendor-specific SRE certifications.

    Hands-on Projects – Real-world experience through chaos engineering experiments, large-scale migrations, or reliability automation.

    Leadership Development – Workshops on incident command, communication, and stakeholder management.

    Continuous Learning – Staying updated with tools like Prometheus, Grafana, Datadog, and emerging AI-driven reliability platforms.

    Conclusion

    Advanced SRE learning paths are not just a career upgrade—they’re a necessity in today’s digital-first world. Engineers who invest in deep technical mastery, observability, security integration, and leadership development will stand out as future-ready SRE leaders.
    By following a structured learning path and continuously adapting to evolving tools, you can move beyond firefighting incidents to designing reliable systems that power business success.
    13.5k Vues
  • Structured Incident Response in SRE: Site Reliability Engineering
    Incident Management in SRE: A Structured Approach to Reliability
    In the world of Site Reliability Engineering (SRE) incident management is a fundamental practice that ensures services remain reliable, resilient, and performant. An incident is any unplanned disruption or degradation of service that affects users. Efficient incident management involves detecting, responding to, resolving, and learning from these disruptions to minimize their impact and prevent recurrence.
    The Role of SRE in Incident Management
    SRE teams are responsible for maintaining the health of large-scale systems. They use engineering approaches to automate operations and improve system reliability. When incidents occur, SREs lead the response efforts, applying a structured and measured approach to restoration.
    SREs focus on reducing Mean Time to Detect (MTTD) and Mean Time to Resolve (MTTR). These metrics help gauge the speed and efficiency of the incident management process. The ultimate goal is not just to fix the issue, but to do so in a way that maintains user trust and organizational reputation.
    Stages of Incident Management
    Detection and Alerting
    Early detection is crucial. SREs set up robust monitoring systems and define Service Level Indicators (SLIs) that trigger alerts when thresholds are breached. Alerts should be actionable, relevant, and prioritized based on severity.


    Response and Triage
    Once an alert is triggered, incident responders assess the scope and severity of the issue. They assign roles such as incident commander, communication lead, and subject matter experts. Clear roles prevent confusion and enable a faster, coordinated response.


    Mitigation and Resolution
    The team works to mitigate the issue, either through automated rollback, failover systems, or manual intervention. The key is to restore service quickly, even if the root cause isn’t fully addressed yet. A temporary fix can be followed by a more permanent solution later.


    Postmortem and Analysis
    After resolution, SREs conduct a blameless postmortem. This review documents the timeline, root cause, impact, and resolution steps. It also identifies process improvements and preventive measures. Blameless culture encourages transparency and learning, rather than fear and blame.


    Best Practices in SRE Incident Management
    Runbooks and Playbooks: Predefined procedures guide responders through common incidents, reducing response time and error.


    On-Call Rotation: SREs take turns being available 24/7 to ensure quick response to critical issues.


    Automated Monitoring and Alerting: Tools like Prometheus, Grafana, and PagerDuty enable fast, data-driven decision-making.


    Communication and Coordination: Keeping stakeholders informed during incidents maintains trust and reduces panic.


    Continuous Improvement: Post-incident insights are used to improve system design, monitoring, and team processes.


    Learn More: https://www.novelvista.com/sre-foundation-training-certification
    7.5k Vues
  • SRE Model: You Should be aware
    Introduction to the SRE Model The SRE model is designed to address the complexities of running software systems at scale. It focuses on creating a balance between releasing new features and ensuring system stability. Unlike traditional operations roles that often focus on manual tasks and firefighting issues, SRE encourages automation, monitoring, and proactive problem-solving. The core idea...
    3.6k Vues
  • Site Reliability Engineering: Meaning, Risk, and Tools
    What is Site Reliability Engineering? Site Reliability Engineering (SRE) is a discipline that combines software engineering and IT operations to ensure high reliability, availability, and performance of large-scale systems. Originally developed by Google, SRE applies engineering principles to operations work, aiming to create scalable and highly reliable software systems. SRE teams focus on...
    4.1k Vues
  • SRE: A Deep Dive into the Site Reliability Engineering Mindset
    Definition of Site Reliability Engineering Site Reliability Engineering (SRE) is a discipline that blends software engineering with IT operations to ensure reliable and scalable systems. Developed by Google, SRE Training applies engineering principles to automate and improve the reliability of services. The core goal is to create highly available, efficient, and scalable systems using code,...
    2.9k Vues
  • A Comprehensive Overview of the Foundation of Site Reliability Engineering (SRE)
    Introduction to Core Concepts of Site Reliability Engineering (SRE) Site Reliability Engineering (SRE) is a discipline that applies software engineering principles to infrastructure and operations, ensuring systems are scalable, reliable, and efficient. Born at Google, SRE focuses on automating operations tasks to minimize human error and increase system uptime. Key concepts of SRE training...
    4.5k Vues
  • Site Reliability Engineering: Tools, Techniques & Responsibilities
    Introduction to Site Reliability Engineering (SRE) Site Reliability Engineering (SRE) is a modern approach to managing large-scale systems by applying software engineering principles to IT operations. Originally developed by Google, SRE focuses on improving system reliability, scalability, and performance through automation and data-driven decision-making. At its core, SRE bridges the gap...
    2.6k Vues
  • What Is SRE? A Beginner's Guide to Modern Reliability Engineering

    The Evolution of Site Reliability Engineering
    Large-scale system management has changed significantly with the rise of Site Reliability Engineering (SRE) Foundation. It started at Google in the early 2000s when software engineers were given the responsibility of using code to solve operations problems. By introducing a software-centric approach to infrastructure management, this change sought to close the gap between development and operations.

    Flexible in nature, traditional system administration concentrated on resolving problems after they came up. A proactive, engineering-driven model with a focus on automation, dependability, and performance was introduced by SRE. Teams were able to measure and strike a balance between innovation and system stability thanks to concepts like SLAs, SLOs, and error budgets.
    These days, SRE principles are not limited to tech giants. SRE is used by businesses of all sizes to increase uptime, decrease labor, and promote cooperation between the operations and development teams. SRE keeps evolving in response to the growing complexity of systems and the need for resilience; it is essential to the development of scalable, dependable, and effective digital services.
    DevOps vs. SRE: What’s the Difference?
    1. Origin
    DevOps is a cultural movement that emerged to improve collaboration between development and operations.

    SRE was created at Google as a way to apply software engineering to operations tasks.

    While DevOps evolved as a philosophy to break silos, SRE is a concrete set of practices rooted in engineering discipline.
    2. Focus
    DevOps emphasizes faster delivery through automation and collaboration.

    SRE focuses on ensuring reliability, scalability, and performance.

    DevOps is about speed and efficiency; SRE ensures systems stay reliable as they scale.
    3. Approach
    DevOps promotes practices like CI/CD and Infrastructure as Code.

    SRE uses SLAs, SLOs, SLIs, and error budgets to manage risk.

    SRE adds measurable, reliability-focused engineering to the DevOps workflow.
    4. Roles and Teams
    DevOps encourages shared responsibility across teams.

    SRE introduces a dedicated role with strong coding and ops skills.

    SREs often act as reliability guardians, while DevOps promotes a collaborative environment.
    Top Tools Every Site Reliability Engineer Should Know
    Site Reliability Engineers (SREs) Training play a critical role in maintaining the reliability and performance of modern systems. To do this effectively, they rely on a robust toolkit that covers monitoring, automation, logging, and infrastructure management.
    1. Prometheus – An open-source monitoring system that collects time-series data and provides powerful alerting capabilities. It's often the go-to tool for system health checks.
    2. Grafana – Frequently used with Prometheus, Grafana offers rich dashboards and visualization for system metrics, helping teams quickly detect anomalies.
    3. ELK Stack (Elasticsearch, Logstash, Kibana) – This trio helps with centralized logging and data analysis. SREs use it to search logs, identify root causes, and track trends over time.
    4. Chaos Monkey – Developed by Netflix, this chaos engineering tool randomly terminates instances in production to test a system’s resilience and recovery strategy.
    5. Kubernetes – A container orchestration platform that automates deployment, scaling, and management of containerized applications, making it essential for managing complex infrastructure.
    6. Terraform – A leading Infrastructure as Code (IaC) tool used to automate infrastructure provisioning and ensure consistency across environments.
    The Future of SRE
    In 2025, Site Reliability Engineering (SRE) is adapting to new demands as technology advances. One significant trend is increasing use of AI and machine learning in incident response and observability. SREs use predictive analytics to identify and fix problems before affecting users.


    Another shift is the rise of platform engineering, where internal developer platforms (IDPs) streamline infrastructure and reliability practices across teams. SREs are playing a key role in building and maintaining these platforms.
    Security and compliance are also becoming core responsibilities, with reliability now extending to areas like zero-trust architecture and data governance.
    Additionally, multi-cloud and edge computing environments are challenging SREs to rethink monitoring, automation, and resilience strategies.
    SREs are not just problem solvers—they’re strategic partners driving innovation, scalability, and trust in digital systems.
    Uncover details: https://www.novelvista.com/sre-foundation-training-certification
    WWW.NOVELVISTA.COM
    Site Reliability Engineering (SRE) Foundation Certification Training in Switzerland
    Advance Operational Reliability: SRE Foundation Certification Training in Switzerland | Master Site Reliability Engineering Skills for Excellence & Career Growth
    20.5k Vues
  • Getting Started with Site Reliability Engineering
    Understanding Site Reliability Engineering In the evolving world of IT and cloud infrastructure, one discipline has emerged as a game-changer: Site Reliability Engineering (SRE). Born at Google, SRE is a practice that blends software engineering with IT operations to ensure scalable and highly reliable systems. What is SRE? Site Reliability Engineering is a methodology that applies software...
    4.2k Vues